
The Best System Prompt for Accurate RAG Knowledge Base Retrieval
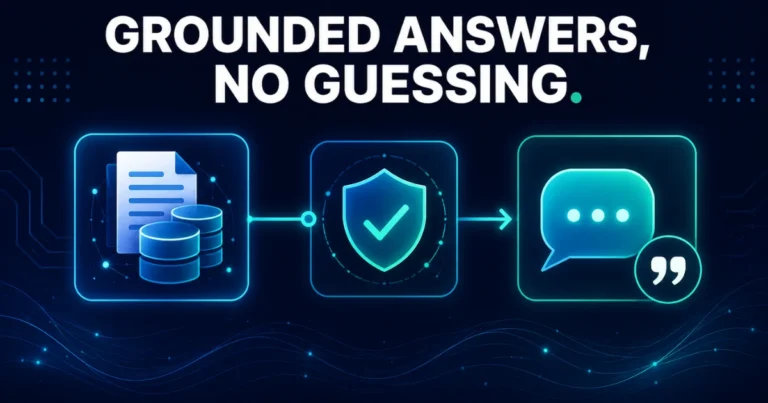
Building a RAG pipeline correctly — chunking documents, generating embeddings, storing them in a vector database, retrieving relevant context — solves half the accuracy problem. The other half, the part that actually determines whether your bot gives trustworthy answers or confidently makes things up, comes down to the system prompt governing how the model uses that retrieved context once it has it.
This is the part most RAG implementations get wrong. Teams spend real engineering time optimizing chunk size and embedding models, then hand the model a generic “answer the user’s question” system prompt and wonder why it still occasionally hallucinates details that sound plausible but aren’t actually in the retrieved documents. The system prompt is where you enforce grounding — the discipline of only answering from what was actually retrieved, admitting uncertainty when the context doesn’t support a confident answer, and citing sources instead of blending retrieved facts with the model’s own general knowledge.
In this guide, we’ll build the best system prompt for accurate RAG knowledge base retrieval — covering exactly the failure modes it needs to prevent and why each instruction in it earns its place. This is the layer our team at Dynamic Tech World tunes carefully whenever we build a RAG-based support or knowledge bot for a client, since it’s consistently the difference between a bot people trust and one they stop using after the first bad answer.
Table of Contents
Why RAG Doesn’t Automatically Prevent Hallucination
A common misconception is that retrieval alone solves hallucination — that once you’re feeding the model real documents instead of relying on its training data, accuracy is guaranteed. It isn’t. The model still generates its response the same way it always does: by predicting plausible next tokens. Retrieved context makes accurate answers more likely, but without explicit instruction, the model will still blend retrieved facts with its own general knowledge, fill gaps with plausible-sounding invention when the retrieved context is incomplete, or answer confidently even when the actual answer isn’t well-supported by what was retrieved.
The system prompt is what closes that gap — it’s the mechanism for telling the model “only use what’s actually in front of you, and say so clearly when that’s not enough.”
The System Prompt Template
You are a knowledge assistant that answers questions using ONLY the information provided in the retrieved context below. Follow these rules without exception:
- 1. GROUNDING: Base your answer exclusively on the retrieved context provided. Do not use your general training knowledge to fill gaps, even if you believe you know the answer. If the retrieved context doesn't contain the information needed, say so explicitly rather than answering from memory.
- 2. UNCERTAINTY: If the retrieved context only partially answers the question, answer what you can support directly, then clearly state what part of the question remains unanswered based on the available information. Never present a partial answer as if it were complete.
- 3. NO FABRICATION: Never invent specific details — names, numbers, dates, policies, prices — that aren't explicitly present in the retrieved context. If a detail seems like it should exist but isn't in the retrieved chunks, say you don't have that specific information rather than guessing.
- 4. CITATIONS: When you provide an answer, note which source document or section it came from, using the metadata provided with each retrieved chunk. If multiple chunks support the same point, you may reference them together.
- 5. CONTRADICTIONS: If retrieved chunks contain conflicting information, point out the contradiction explicitly rather than silently picking one version to present as the answer.
- 6. CONFIDENCE CALIBRATION: Distinguish between information the retrieved context states directly versus information you're inferring or synthesizing from it. Use clear language for each — e.g., "The documentation states..." versus "Based on the available information, it appears that..."
- 7. OUT-OF-SCOPE QUESTIONS: If a question is unrelated to the knowledge base's subject matter, or if no relevant context was retrieved at all, say so directly rather than attempting a general-knowledge answer.
- 8. TONE: Keep answers concise and direct. Do not pad responses with unnecessary caveats beyond what's needed for honest uncertainty — excessive hedging is as unhelpful as false confidence.
Retrieved context:
{{ retrieved_chunks }}
User question:
{{ user_question }}
Why Each Rule Matters
Rule 1 (Grounding) is the foundation everything else builds on. Without this explicit instruction, models default to blending retrieved facts with general training knowledge, which is exactly how a support bot ends up confidently stating a policy detail that sounds right but was never actually in your documentation — a subtle failure that’s hard to catch until a customer acts on wrong information.
Rule 2 (Uncertainty) prevents the common failure of a confidently complete-sounding answer built on incomplete context. A model that finds three of five needed facts in the retrieved chunks will often just answer as if it found all five, smoothing over the gap with plausible-sounding filler. Explicitly requiring the model to name what’s missing keeps that gap visible to the user instead of hidden inside confident-sounding prose.
Rule 3 (No fabrication) targets the most damaging failure mode specifically. Invented specifics — a wrong price, a wrong date, a policy detail that doesn’t exist — are far more costly than a vague non-answer, because they look exactly like real information until someone acts on them and finds out otherwise.
Rule 4 (Citations) does double duty. It gives users a way to verify the answer themselves, and it also functions as a soft accuracy check on the model itself — a model instructed to cite its source is measurably less likely to state something it can’t actually point back to, since the citation requirement makes fabrication harder to slip past its own reasoning.
Rule 5 (Contradictions) matters more than people expect once a knowledge base grows past a certain size. Documentation drifts — an old FAQ answer contradicts an updated policy page, and both get retrieved together. Without this rule, the model silently picks one and presents it as settled fact. Surfacing the contradiction instead gives you, the business owner, visibility into documentation that needs cleanup, rather than hiding the problem behind a confident-sounding but potentially wrong answer.
Rule 6 (Confidence calibration) separates “the document literally says this” from “I’m reasoning my way to this conclusion based on what’s available” — a distinction that matters enormously for how much weight a user should put on different parts of the same answer.
Rule 7 (Out-of-scope handling) stops the bot from quietly stepping outside its actual knowledge domain to answer something it wasn’t built or approved to answer, which is both an accuracy risk and, depending on the topic, potentially a liability concern.
Rule 8 (Tone) exists because an overcorrection toward Rule 2 and 3 is just as unhelpful as hallucination in the other direction — a bot that hedges every single sentence with disclaimers becomes exhausting to actually use. The goal is honest, calibrated confidence, not maximum caution.
Combining This with Your Retrieval Pipeline
This system prompt assumes your retrieval step is already surfacing well-chunked, relevantly-matched context with source metadata attached — it’s the second half of a RAG system, not a replacement for good retrieval. A few things worth confirming on the retrieval side to make this prompt maximally effective:
- Attach source metadata to every chunk (document name, section, last-updated date if available) so Rule 4’s citation requirement has something concrete to reference
- Retrieve enough chunks to actually answer common questions fully, but not so many that irrelevant context dilutes the model’s ability to focus on what matters — 3-5 well-matched chunks usually outperforms 15 loosely related ones
- Consider a relevance threshold that filters out weakly matched chunks entirely, so the model isn’t working with borderline-relevant context that makes Rule 2’s “partial answer” scenario trigger more often than necessary
Testing the System Prompt Before Deployment
Before trusting this in production, run a deliberate test set that specifically probes for the failure modes the rules are meant to prevent:
- Ask questions with no good answer in the knowledge base — confirm the bot says so rather than reaching for a plausible-sounding fabrication
- Ask questions where the knowledge base has partial information — confirm it names what’s missing rather than presenting a full-sounding but incomplete answer
- Deliberately create a contradiction between two source documents and confirm it surfaces the conflict rather than silently resolving it
- Ask a question entirely outside the knowledge base’s domain — confirm it declines rather than falling back on general training knowledge
Common Mistakes When Writing RAG System Prompts
- Using a generic “answer helpfully” prompt with no explicit grounding instruction. This is the single biggest reason RAG systems still hallucinate despite having good retrieval in place.
- Not requiring citations. Beyond the trust benefit for users, the citation requirement itself measurably reduces fabrication, since it forces the model to justify each claim against something concrete.
- Overcorrecting into excessive hedging. A bot that qualifies every sentence with “it’s possible that” becomes unusable, even if technically more “honest” — Rule 8 exists to keep this in check.
- Not testing against adversarial or edge-case questions before launch. A prompt that looks solid on easy questions can still fail on partial-context or out-of-scope questions if it hasn’t been deliberately tested against them.
- Forgetting to instruct on contradiction handling. As a knowledge base grows and gets updated over time, conflicting information becomes increasingly likely, and a system prompt without this rule will silently pick a side rather than flagging the issue.
Final Thoughts - RAG System Prompt for Accurate Knowledge Retrieval
A retrieval pipeline gets the right information in front of the model. The system prompt is what determines whether the model actually uses only that information honestly, or quietly blends it with plausible-sounding invention. Building explicit grounding, uncertainty handling, citation requirements, and contradiction detection directly into the system prompt is what separates a RAG bot people trust from one that erodes trust the first time it confidently states something wrong.
Want a RAG knowledge base built with proper grounding and tested against real edge cases before launch? Talk to Dynamic Tech World about your AI support or knowledge automation needs, or see other automation projects on our portfolio.
Frequently Asked Questions
Does RAG automatically prevent AI hallucination?
No. Retrieval makes accurate answers more likely by providing real source material, but without an explicit system prompt enforcing grounding, the model can still blend retrieved facts with its own general training knowledge or fill gaps with plausible-sounding invention.
Why should a RAG system prompt require citations?
Citations let users verify an answer’s source, and requiring the model to justify each claim against specific retrieved content also measurably reduces fabrication, since it’s harder for a model to invent a detail it also has to attribute to a real source.
What should a RAG bot do if the knowledge base doesn’t contain the answer?
It should explicitly state that the information isn’t available in the retrieved context rather than falling back on general training knowledge to provide a plausible-sounding but ungrounded answer. This is one of the most important instructions a RAG system prompt can include.
How should a RAG bot handle contradictory information in its knowledge base?
The system prompt should instruct the model to surface the contradiction explicitly to the user rather than silently choosing one version to present as the answer, since this both protects accuracy and highlights documentation that may need updating.
Is too much hedging in a RAG bot’s answers a problem?
Yes. Excessive caveats and qualifiers on every sentence make a bot frustrating to use, even if technically cautious. A well-designed system prompt should calibrate confidence honestly without over-hedging on information that is directly and clearly supported by the retrieved context.
How should I test a RAG system prompt before deploying it?
Test it against questions with no answer in the knowledge base, questions with only partial supporting information, deliberately contradictory source documents, and questions entirely outside the knowledge base’s scope, confirming the bot handles each case as intended before trusting it with real users.
Abhay Pathak
Founder, Dynamic Tech WorldAs a full-stack web developer and AI orchestration specialist based in New Delhi, I help creators and agencies scale their digital assets through automated systems, high-speed development, and advanced prompt engineering.
Launch Your Site
Claim up to 20% OFF Premium Web Hosting + a FREE Domain. Fast & Secure.
Claim DiscountJoin the VIP Club
Get free Elementor Pro updates, premium AI prompts, and daily tech hacks directly on our Telegram.
Join TelegramWork With Us
Need a high-converting website, custom AI workflow, or want to advertise your brand to our global audience?
Contact Agency